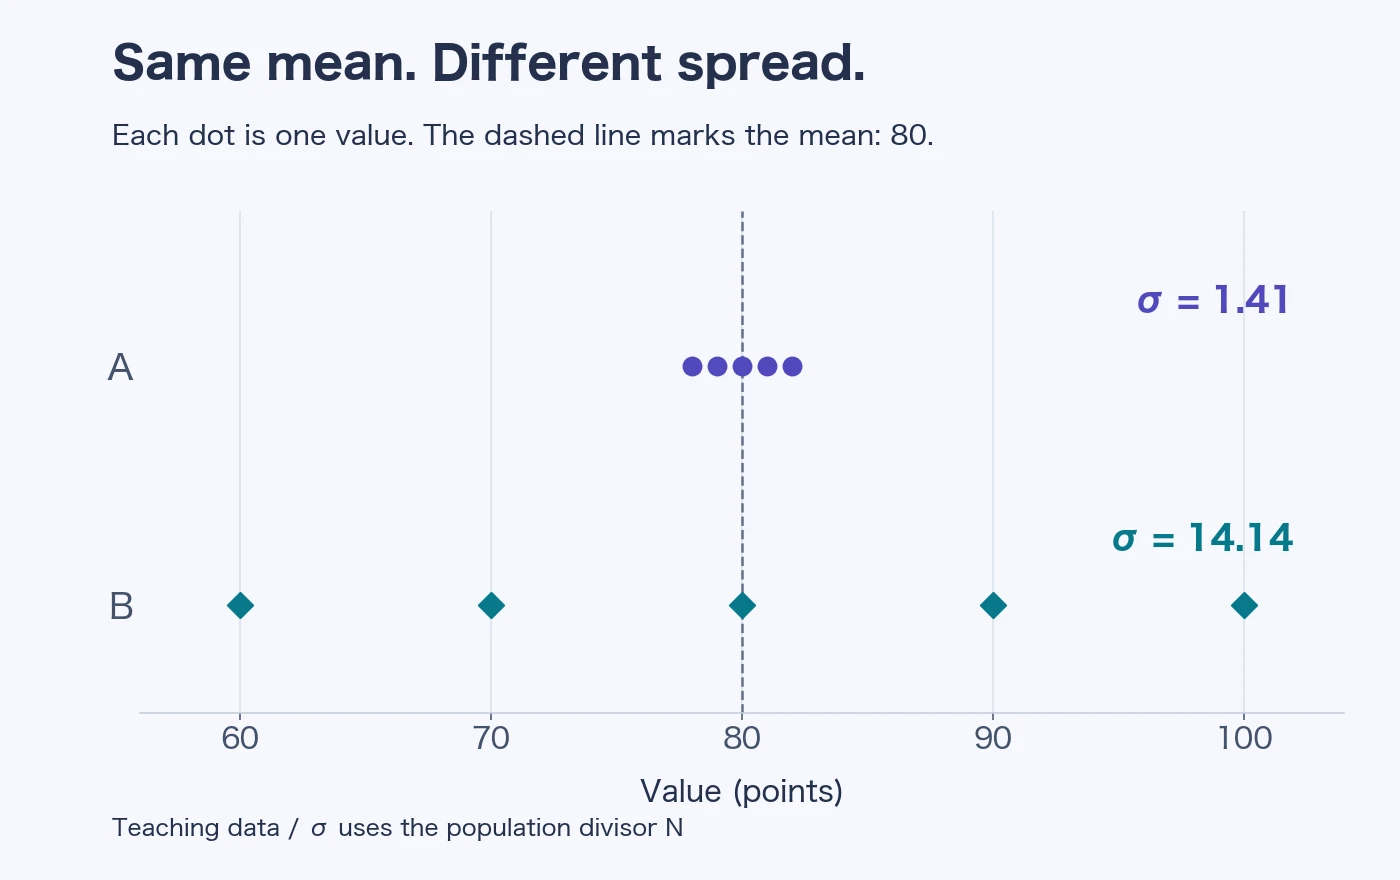
When summarizing exam marks, replicate lab measurements, or sales figures, two pitfalls trip up students and analysts alike: 1) relying solely on the arithmetic mean when a single outlier skews the dataset, and 2) getting a different standard deviation from Excel (STDEV.S vs. STDEV.P) because of the $N$ versus $N-1$ denominator.
To summarize any dataset accurately, always pair a measure of center (location) with a matching measure of spread (scale), and explicitly state whether your standard deviation divides by $N$ (population) or $N-1$ (sample):
This guide presents a 4-step indicator selection workflow, a step-by-step worked table for 5 scores, an $N$ vs. $N-1$ conversion and standard error table, and a quantitative comparison of mean/SD versus median/IQR on skewed data.
4-Step Decision Workflow for Choosing Statistical Indicators
Select the right summary statistics in four steps based on distribution shape and study design:
Use the arithmetic mean $\bar{x}$ for roughly symmetric distributions or when the total sum matters; use the median for skewed data or datasets with extreme outliers.
→ Report both Mean and Median when in doubtPair the mean with standard deviation ($\sigma$ or $s$); pair the median with the outlier-resistant interquartile range ($\text{IQR} = Q_3 - Q_1$).
→ Screen outliers via $Q_1 - 1.5\text{IQR}$ to $Q_3 + 1.5\text{IQR}$Use divisor $N$ ($\sigma$, `STDEV.P`) when your dataset is the entire population of interest; use $N-1$ ($s$, `STDEV.S`) when estimating population spread from a sample.
→ Convert via $s = \sigma \times \sqrt{N/(N-1)}$Use Coefficient of Variation ($\text{CV} = \sigma/\bar{x}$) to compare spread across different units, and Standard Error ($\text{SE} = s/\sqrt{N}$) for uncertainty in the estimated mean.
→ Never confuse data spread (SD) with mean precision (SE)Comparison of 6 Core Location and Spread Measures
Based on the NIST/SEMATECH e-Handbook and OpenStax Introductory Statistics 2e:
| Indicator (Symbol) | Category | Formula / Definition | Units | Outlier Resistance | Primary Use Case & Decision Rule |
|---|---|---|---|---|---|
| Arithmetic Mean ($\bar{x}$) | Location | $\bar{x} = \dfrac{1}{N}\sum_{i=1}^{N} x_i$ | Same as data | Low (pulled by extremes) | Symmetric measurements and totals where every unit counts equally |
| Median ($M_e$) | Location | Middle value after sorting (average of two middle values if $N$ is even) | Same as data | High (Robust) | Skewed distributions (income, housing prices, latency) |
| Population SD ($\sigma$) | Spread | $\sigma = \sqrt{\dfrac{1}{N}\sum_{i=1}^{N}(x_i - \bar{x})^2}$ | Same as data | Low (squaring amplifies outliers) | Descriptive spread of a complete finite group (STDEV.P) |
| Sample SD ($s$) | Spread | $s = \sqrt{\dfrac{1}{N-1}\sum_{i=1}^{N}(x_i - \bar{x})^2}$ | Same as data | Low (squaring amplifies outliers) | Inferential spread from $N$ replicate measurements (STDEV.S) |
| Interquartile Range ($\text{IQR}$) | Spread | $\text{IQR} = Q_3\text{ (75th %ile)} - Q_1\text{ (25th %ile)}$ | Same as data | High (trims top/bottom 25%) | Robust spread paired with median; boxplot outlier fences |
| Coefficient of Variation ($\text{CV}$) | Relative Spread | $\text{CV} = \dfrac{\sigma}{\bar{x}}$ (or $\dfrac{s}{\bar{x}}$) | Dimensionless (% / ratio) | Low | Comparing dispersion across different scales or units |
Worked Example 1: Mean, Median & Standard Deviation for 5 Scores
Let us work through the five test scores 85, 92, 78, 90, 88 step by step.
Step 1: Mean and Median
- Sum: $85 + 92 + 78 + 90 + 88 = \mathbf{433}$
- Mean $\bar{x}$: $433 \div 5 = \mathbf{86.6\text{ points}}$
- Median: Sort ascending $\rightarrow$
78, 85, 88, 90, 92. The 3rd of 5 sorted values is $\mathbf{88\text{ points}}$. (For an even count like78, 85, 88, 92, average the two middle values: $(85 + 88) \div 2 = 86.5$.)
Step 2: Sum of Squared Deviations ($SS$) and Standard Deviation
| Observation $i$ | Score $x_i$ | Deviation $x_i - 86.6$ | Squared Deviation $(x_i - 86.6)^2$ | Verification Note |
|---|---|---|---|---|
| $1$ | $85$ | $-1.6$ | $2.56$ | $1.6$ below mean (squaring makes all terms non-negative) |
| $2$ | $92$ | $+5.4$ | $29.16$ | $5.4$ above mean |
| $3$ | $78$ | $-8.6$ | $73.96$ | Farthest from mean; contributes $62%$ of total $SS$ |
| $4$ | $90$ | $+3.4$ | $11.56$ | $3.4$ above mean |
| $5$ | $88$ | $+1.4$ | $1.96$ | Median observation |
| Total / Summary | Sum $= 433$ ($\bar{x} = 86.6$) | $\sum = 0.0$ | $SS = 119.20$ | Deviations around the mean always sum to exactly $0$ |
From $SS = 119.20$, apply the appropriate denominator:
-
Population Standard Deviation ($N = 5$, Tools Hub Calculator & Excel
STDEV.P): -
Sample Standard Deviation ($N - 1 = 4$, Unbiased Variance Root & Excel
STDEV.S): -
💡 Load directly in the calculator:
Conversion Multipliers by Sample Size $N$: $\sigma_N$ vs. $s_{N-1}$ and Standard Error $\text{SE}$
Because Tools Hub’s Statistics Calculator outputs population standard deviation $\sigma_N$ (divisor $N$), you can convert to sample standard deviation $s_{N-1}$ (divisor $N-1$) or Standard Error of the Mean ($\text{SE}$) using:
| Sample Size $N$ | Population Divisor $N$ (STDEV.P) |
Sample Divisor $N-1$ (STDEV.S) |
Multiplier $\sqrt{\frac{N}{N-1}}$ ($\sigma_N \rightarrow s_{N-1}$) | Percentage Difference | Standard Error Factor $\frac{1}{\sqrt{N}}$ ($s_{N-1} \rightarrow \text{SE}$) |
|---|---|---|---|---|---|
| $N = 3$ (triplicate) | $3$ | $2$ | $\times 1.224745$ | $+22.47%$ | $\times 0.577350$ |
| $N = 5$ (5 scores) | $5$ | $4$ | $\times 1.118034$ | $+11.80%$ | $\times 0.447214$ |
| $N = 8$ (8 values) | $8$ | $7$ | $\times 1.069045$ | $+6.90%$ | $\times 0.353553$ |
| $N = 10$ (10 runs) | $10$ | $9$ | $\times 1.054093$ | $+5.41%$ | $\times 0.316228$ |
| $N = 30$ (moderate) | $30$ | $29$ | $\times 1.017095$ | $+1.71%$ | $\times 0.182574$ |
| $N = 100$ (large) | $100$ | $99$ | $\times 1.005038$ | $+0.50%$ | $\times 0.100000$ |
Paste Spreadsheet Columns or Comma-Separated Numbers
Compute Count, Sum, Mean, Median, Min/Max & Standard Deviation Instantly
Paste values separated by newlines, commas, spaces, or tabs to verify your summary statistics and copy a formatted report block in one click.
Worked Example 2: Symmetric vs. Outlier-Skewed Datasets (Mean/SD vs. Median/IQR)
See how a single extreme observation alters the mean and standard deviation while leaving the median and central quartiles stable:
| Dataset Scenario | Sorted Values | Mean $\bar{x}$ | Median | Population SD $\sigma_N$ | Interquartile Range $\text{IQR} = Q_3 - Q_1$ | Key Interpretation |
|---|---|---|---|---|---|---|
| 1. Symmetric (No Outliers) | 300, 350, 400, 450, 500 |
400.0 | 400.0 | 70.71 | $475 - 325 = \mathbf{150}$ | Mean and median coincide; $\bar{x} \pm \sigma$ summarizes data well |
| 2. Single High Outlier | 300, 350, 400, 450, 5000 |
1,300.0 ($+225%$) | 400.0 (unchanged) | 1,850.68 ($26.2\times$) | Hinge spread $= \mathbf{100}$ ($450 - 350$) | One 5000 value inflates mean to 1,300; median stays at 400 |
| 3. Weekly Sales (1 Promo Day) | 11, 12, 12, 13, 14, 15, 90 |
23.86 | 13.0 | 27.03 | $15 - 12 = \mathbf{3.0}$ | Typical daily volume is median 13 ($\text{IQR} = 3$); log promo separately |
- 💡 Load directly in the calculator: Open the outlier check dataset (300, 350, 400, 450, 5000) in the Statistics Calculator
Connected Statistical Workflows
Once you have verified your mean and standard deviation:
- Standardize individual scores into T-scores and percentiles: Use our Deviation Score (T-Score) Guide and Deviation Score Calculator.
- Fit a linear regression ($y = ax + b$) and $R^2$: Use our Least Squares Regression Guide and Least Squares Calculator.
- Propagate measurement uncertainty through formulas: Use our Error Propagation Calculator and Significant Figures Guide.
Verification Scope
All definitions, worked tables, and $N$ vs. $N-1$ conversion factors in this guide were verified on October 27, 2026 against OpenStax Introductory Statistics 2e, the NIST/SEMATECH e-Handbook, and Microsoft Excel function documentation. Explore more math and data tools in the Mathematics Category.
FAQ
When should I divide by N (population SD) versus N−1 (sample SD)?
Divide by N (population standard deviation σ, Excel STDEV.P) when your numbers represent the entire group of interest—such as every student in a specific class test. Divide by N−1 (sample standard deviation s, Excel STDEV.S) when your numbers are a sample drawn from a larger population—such as 5 replicate lab measurements—because Bessel's correction (N−1 degrees of freedom) corrects the downward bias in sample variance. Tools Hub's Statistics Calculator displays the N-divisor population SD.
If the mean and median differ sharply, which one should I report?
When a dataset is skewed or contains extreme observations (such as household incomes or promotional sales spikes), the mean is pulled strongly toward the tail while the median remains anchored at the middle rank. For example, in [300, 350, 400, 450, 5000], the mean is 1,300 (higher than 4 of the 5 values), whereas the median is 400. Best practice in technical reports is to state both the mean and the median side by side.
What is the difference between standard deviation (SD) and standard error (SE / SEM)?
Standard deviation (σ or s) measures how widely individual observations scatter around the mean. Standard error of the mean (SE = s / √N) measures the precision of the sample mean itself as an estimate of the true population mean. Increasing sample size N shrinks SE proportionally to 1/√N, whereas SD converges toward the true population spread rather than zero.
How do I compare spread across datasets with different units or vastly different means?
Because standard deviation carries the original measurement units, you cannot directly compare raw SD values between centimetres and kilograms or between means that differ by 10×. Instead, compute the dimensionless Coefficient of Variation: CV = SD / Mean.
How does the 1.5 × IQR rule flag potential outliers?
Subtract the 25th percentile (first quartile Q₁) from the 75th percentile (third quartile Q₃) to obtain the interquartile range IQR = Q₃ − Q₁. Tukey's boxplot fence flags observations below Q₁ − 1.5 × IQR or above Q₃ + 1.5 × IQR as potential outliers. Always inspect flagged points for data-entry or instrument errors rather than deleting them blindly.