If an essay fits your counter but exceeds a submission form, first check what each system calls a character. Width, visual symbols, Unicode code points and encoded bytes are different measurements.
Open the text tools and character counter to compare the examples below. Use sample text rather than confidential material.
Which count do you need?
| Requirement | Measure to check | Limitation |
|---|---|---|
| Essay or application character limit | The recipient’s specified method | Document scope, spaces and footnotes may differ |
| Tools Hub character count | Unicode code points | Includes spaces and newlines; not visual symbols |
| JavaScript length or some form limits | UTF-16 code units | 😀 uses two units; check the particular form |
| API or database byte limit | Bytes in its required encoding | This tool reports UTF-8, not other encodings |
Unicode UAX #29 describes grapheme clusters, which approximate user-perceived characters. This counter instead iterates the string by code point, as described by MDN’s string iterator documentation.
Emoji and combining characters: reproducible values
“Visual groups” assumes a font that renders each sequence as one grapheme. Values refer to the exact sequence shown, before normalization.
| Input | Visual groups | Tool’s code points | UTF-16 units | UTF-8 bytes |
|---|---|---|---|---|
| A | 1 | 1 | 1 | 1 |
| A | 1 | 1 | 1 | 3 |
| あ | 1 | 1 | 1 | 3 |
| 😀 | 1 | 1 | 2 | 4 |
| é | 1 | 1 | 1 | 2 |
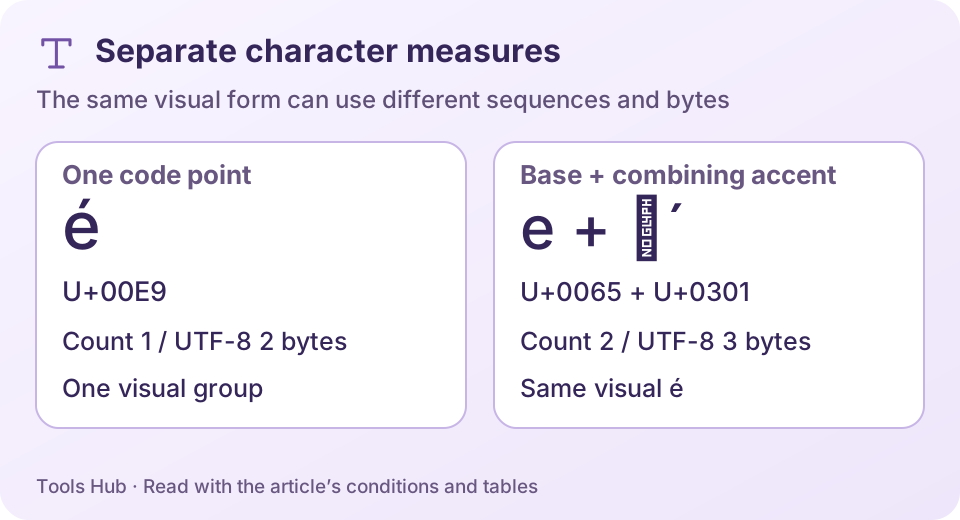
| é (combined) | 1 | 2 | 2 | 3 |
| 🇯🇵 | 1 | 2 | 4 | 8 |
| 👨👩👧👦 | 1 | 7 | 11 | 25 |
The single é is U+00E9; combined é is U+0065 U+0301. The flag contains two regional indicators; the family sequence has four person characters and three zero-width joiners.
Do not remove symbols just to match another counter before checking its rules. Normalization can also change counts; retain the original text and follow the destination’s requirements.
A two-line example: 3 characters, 5 bytes, 2 lines
Paste these two lines with no newline after あ:
A
あ
A contributes 1 code point and 1 byte, LF contributes 1 and 1, and あ contributes 1 and 3. The counter should show 3 characters, 5 bytes, 2 lines. Empty input has 0 lines; A alone has 1.
Spaces, full-width spaces and tabs count too. A trailing newline adds another code point and line. Textareas normally expose LF newlines; this is not the on-disk size of a file with CRLF, a BOM or another encoding.
Check a submission and recount transformed output
- Check whether the destination includes whitespace, footnotes and other document sections, and whether its limit is characters or bytes.
- Paste into the counter’s Input field. All three counters measure Input, not Output.
- If you transform capitalization or whitespace, review Output, copy it back into Input and recount. Preserve your original document.
“Remove blank lines” edits the text and places the result in Output. It is not a separate counter that excludes every whitespace character.
Check with a small example
A, a newline and あ: 3 code points, 5 bytes
Counting updates as you type. Copy transformed output back into Input to recount it.
Frequently asked questions
Which value is correct if Word disagrees?
Both can follow different definitions or include different document content. If the recipient specifies Word’s count, use that method and its required settings. This counter cannot certify compliance with every submission rule.
Are all Japanese characters three UTF-8 bytes?
No. For example, 𠮷 (U+20BB7) uses four. RFC 3629 specifies UTF-8 encoding with one to four bytes per code point.
Can I exclude all whitespace from the displayed count?
The current counter includes whitespace. It has no dedicated whitespace-excluding count. Whitespace transformation changes the text; check whether that operation matches the recipient’s definition.
How can I return for the next assignment?
Use the tool’s “Add to favorites” control to find it in My Tools on the same browser. Favorites do not save or synchronize your document. Another browser or cleared site storage needs a new registration.
Verification scope and next steps
On 24 October 2026, the Unicode, MDN and RFC definitions were compared with the implementation’s code-point iteration, UTF-8 encoding and line splitting. The table sequences and two-line example are the verification cases. Rules in individual document editors and submission systems are outside this scope.
Continue to case conversion for editing, or bytes, GB and GiB for storage limits.